Promoted
Jev AI Model
freemiumJev AI Model pairs a free playground with an API for turning text or JSON state into typed classifications, scores, and yes/no probability outputs.
AIDeveloper ToolAnalytics
What it does, who it helps, and how it fits into your workflow.
fal is a developer platform for generative media. It provides a gallery of production models for image, video, audio, and 3D generation, plus serverless GPUs and on-demand compute for deploying and scaling custom models.
Developers use fal to call models through APIs, run inference without managing infrastructure, and scale custom work with H100, H200, and B200 GPUs. The platform is aimed at engineering teams that need model choice and predictable throughput rather than a browser-only creative studio.
The official site describes access to more than 1,000 production-ready models and a globally distributed serverless engine. Usage is metered, so the service is classified as paid.
Call image, video, audio, and 3D models from one platform. Pricing is generally based on output, image size, video duration, tokens, or model-specific usage.
Run models without configuring GPU autoscaling or cold-start infrastructure. This lets product teams prototype and deploy behind fal’s runtime.
Access H100, H200, and B200 capacity for custom models and heavier workloads. The pricing page lists H100 capacity from $1.89 per hour.
Enterprise plans add assistance for scaling, integration, and production deployment.
fal is classified as paid because its core developer platform uses metered model and GPU pricing. The official pricing page lists model APIs by output or usage and GPU capacity by hour; for example, H100 capacity is listed from $1.89 per hour. Image models may bill by image or megapixel, while video and language models use duration- or token-based billing.
Exact cost depends on model, resolution, quality, input references, and traffic. Enterprise terms are custom. Developers should run a small benchmark before estimating production spend.
Strengths
Limitations
Compare fal with Atlas Cloud and WaveSpeedAI when unified multimodal APIs and free starting credits are important. Choose fal when serverless GPU deployment, custom model operation, and a large model gallery are the primary requirements.
The core model and GPU platform is metered. The site has free utility pages, but production inference is paid.
Model APIs are generally billed by output, image size, duration, or tokens; GPU capacity is billed by hour.
Yes. It offers serverless GPUs and on-demand H100, H200, and B200 capacity.
Teams needing enterprise scale, custom deployment, or volume-based support should use the enterprise contact.
Jev AI Model pairs a free playground with an API for turning text or JSON state into typed classifications, scores, and yes/no probability outputs.
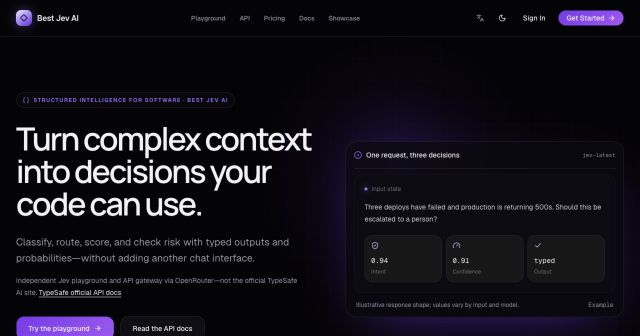
Best Jev AI pairs a free playground with an OpenRouter gateway for turning text or JSON context into typed choices, scores, and yes/no probabilities.
Browse Rush Ounza’s public software-engineering portfolio, including machine-learning notebooks, web projects, activities, and background.